On this page
Illustration generated with Cloudflare Workers AI (FLUX.2 klein)
Updated 18 Nov 2026: replaced the 2025 model list with current open-weight models, sized the hardware tiers by memory, fixed the text-generation-webui install command that no longer works, corrected the cost example and added our own GPU, CPU-only and container test results.
Self-hosting an LLM means running an open-weight model, such as Qwen3.5, Gemma 4 or gpt-oss, on your own hardware with a tool like Ollama or llama.cpp. Memory decides what you can run. At 4-bit, an 8B or 9B model needs about 5 to 6 GB, gpt-oss-20b about 12 GB and a 27B model about 17 GB. Self-hosting keeps your prompts on your machine. On cost alone, a cheap API model often wins.
We checked every model, command and price below against primary sources on 17 and 18 Nov 2026. We ran three 4-bit models, from 4B to 9B, with every layer on an 8 GB AMD Radeon RX 5700 XT, then ran the same three on the CPU alone. On the GPU, Qwen3.5-9B wrote 53 tokens a second; on 6 CPU cores it wrote under 3. We also ran one model on an M1 MacBook Air. On our home server, we ran the textgen install steps, Ollama and Open WebUI in containers. We only tested models that fit in 8 GB, so the larger tiers come from NVIDIA’s spec pages and the model files.
Tested by our setup on 18 Nov 2026
- What we did: ran Qwen3.5-4B, Llama 3.1 8B and Qwen3.5-9B (4-bit) with every layer on an 8 GB GPU and again CPU-only, and measured speed and memory; ran llama-server and checked what it listens on; ran Ollama from its Linux tarball and Open WebUI through uvx; ran Qwen3.5-4B on an M1 MacBook Air. On 17 Nov 2026 we ran the textgen install steps, Ollama and Open WebUI in containers on our home server
- On: AMD Radeon RX 5700 XT 8 GB (Vulkan, Mesa RADV 26.1.6) passed through to a Debian 13 VM with 6 vCPUs (Intel Core i5-9400F), llama.cpp b12445, Ollama 0.40.16, Open WebUI 0.13.4; Apple M1 MacBook Air, 8 GB, macOS 27.3, llama.cpp 1.0.0 (Metal); Intel Core i3-7100 home server, Debian 13, Docker 29.9.3 (containers capped at 1 CPU and 2 GB), with Debian 13 and Ubuntu 24.04 images, textgen c93f887, Ollama 0.40.16, Open WebUI 0.13.3
- When: 18 Nov 2026 (home server: 17 Nov 2026)
- Not tested: models or VRAM tiers above 8 GB, NVIDIA cards, partial GPU offload, 70B models, vLLM, LM Studio, Jan, GPT4All, offline use, power draw at the wall
Key takeaways
- Self-hosting keeps your data on your hardware, but only if you use local models, turn off cloud features and keep the ports on 127.0.0.1.
- Memory decides what runs. At 4-bit, 8 GB of VRAM fits 4B to 9B models (we ran three on an 8 GB card), 16 GB fits gpt-oss-20b, and 27B to 31B models need 24 GB or more.
- On our 8 GB card, 4B to 9B models wrote 53 to 86 tokens a second. With no GPU the same models still ran, at 2.75 to 5.92 tokens a second on 6 CPU cores.
- On cost alone, today’s cheapest API models often beat a self-hosted box. Run your own numbers with the formula in the cost section.
- Ollama, llama.cpp and textgen (formerly text-generation-webui) are the easiest ways in. We ran all three for this update.
What self-hosting an LLM gets you in 2026
Self-hosting an LLM means the model runs on hardware you control instead of on a provider’s servers. You get privacy, no per-token fees and offline use, but each depends on how you set it up:
- Privacy: prompts and documents stay on your machine when you run local models. Ollama’s FAQ says “We don’t see your prompts or data when you run locally”, but Ollama also offers cloud models, which are processed by Ollama. Turn that off (see Privacy considerations).
- No per-token fees: you still pay for the hardware, the power and your own time to maintain it.
- Customization: you can fine-tune open-weight models for your own data, for example with LoRA. Check the license first: Llama’s terms also apply to Llama fine-tunes.
- Offline use: once a model is downloaded, it runs without internet. LM Studio’s docs note that search, model downloads and app updates still need a connection. We did not test offline use.
- No rate limits or quotas: your hardware’s speed is the only limit.
How to build a privacy-first local AI server in 2026
Hardware requirements
The main limit is memory. To run at full speed, a model’s 4-bit file has to fit in your GPU’s VRAM with room left for context. If it does not fit, llama.cpp and Ollama keep some layers in system RAM, which works but is slower. You do not need a big CPU to start: our 6-core test VM ran every model we tried, from 4B to 9B, with no GPU at all, just slowly.
| VRAM | Example cards | What fits at 4-bit (weights only) |
|---|---|---|
| 8 GB | RTX 5060, RTX 5060 Ti 8 GB, Radeon RX 5700 XT (our test card) | 4B to 9B models: Qwen3.5-4B, Llama 3.1 8B, Qwen3.5-9B (all three tested) |
| 12 GB | RTX 4070, RTX 5070 | Up to about 12B to 14B: Gemma 4 12B, Ministral 3 14B, Phi-4 |
| 16 GB | RTX 4080, RTX 4070 Ti SUPER, RTX 5080, RTX 5070 Ti, RTX 5060 Ti 16 GB | gpt-oss-20b and dense models up to about 20B. Not a 27B model at Q4_K_M |
| 24 GB | RTX 4090 | 27B to 31B: Qwen3.8-27B, Gemma 4 31B |
| 32 GB | RTX 5090 | 27B to 31B, with more room for context |
| 48 GB and up | Two 24 GB cards or a 48 GB workstation card | 70B at Q4_K_M (42.5 to 43.1 GB) |
Card memory is from NVIDIA’s RTX 40 and RTX 50 spec pages, and for the RX 5700 XT from our own card. Model sizes are the 4-bit GGUF files on Hugging Face and llama.cpp’s quantization table, checked 17 Nov 2026. Context needs memory on top of the weights. On our 8 GB card with an 8,192-token context, Llama 3.1 8B used 5.44 GiB of VRAM, 1 GiB of it for the context cache. Qwen3.5-9B used 5.33 GiB: its design needs a smaller context cache, and llama.cpp keeps each model’s token embedding table in system RAM.
Entry level: 8 to 12 GB of VRAM
- 8 GB in practice: on our RX 5700 XT, Qwen3.5-4B, Llama 3.1 8B and Qwen3.5-9B each loaded with all 33 layers on the GPU at an 8K context, using 3.09 to 5.44 GiB of the card’s 7.98 GiB.
- A 13B model is past the 8 GB line. At Q4_K_M its weights alone are about 8 GB, which leaves no room for context. For 12B to 14B models, use a 12 GB card such as the RTX 4070. The 2025 version’s “8+ GB VRAM (RTX 4070 or better)” line mixed the two up: the RTX 4070 has 12 GB.
- System RAM: 16 to 32 GB, as a guide. Running CPU-only on our test VM, Llama 3.1 8B peaked at 8.04 GiB.
- Storage: a 50 to 100 GB SSD holds several models. 4-bit files at this tier are 2.7 to about 9 GB each.
Mid range: 16 to 32 GB of VRAM
- 16 GB is too little for a 27B model. Qwen3.8-27B’s 4-bit file (Unsloth’s UD-Q4_K_M) is 16.56 GB before any context. For 27B to 31B models, go to 24 GB (RTX 4090) or 32 GB (RTX 5090).
- Mixture-of-experts models stretch this tier. gpt-oss-20b has 21B parameters with 3.6B active, and its model card says it runs “within 16GB of memory”. It needs memory for all 21B weights, but each token uses only 3.6B of them.
- System RAM and storage: enough RAM to hold any layers that do not fit on the GPU. 4-bit files at this tier are 12 to 18 GB each.
High end: 70B models and larger
Llama 3.3 70B at Q4_K_M is a 42.52 GB file, and llama.cpp’s table gives 43.1 GB for Llama 3.1 70B. No card in NVIDIA’s RTX 40 or RTX 50 consumer lines has more than 32 GB. Your options are two 24 GB cards, a 48 GB workstation card, or keeping part of the model in system RAM with llama.cpp’s -ngl option, which is much slower. gpt-oss-120b fits on “a single 80GB GPU”, according to its model card. We did not test a 70B model for this update.
Speed on an 8 GB GPU
On our 8 GB Radeon RX 5700 XT, all three 8 GB picks ran with every layer on the GPU. Qwen3.5-9B wrote 53 tokens a second, so a 200-token answer takes about 4 seconds.
| Model (4-bit) | File size | Prompt (pp512) | Generation (tg128) | VRAM in use at 8K context |
|---|---|---|---|---|
| Qwen3.5-4B Q4_K_M | 2.54 GiB | 1,011.59 t/s | 85.67 t/s | 3.09 GiB |
| Llama 3.1 8B Instruct Q4_K_M | 4.58 GiB | 560.06 t/s | 63.21 t/s | 5.44 GiB |
| Qwen3.5-9B Q4_K_M | 5.28 GiB | 552.26 t/s | 53.39 t/s | 5.33 GiB |
pp512 is reading a 512-token prompt and tg128 is writing 128 tokens, each the mean of 5 runs. llama.cpp’s default flash attention setting, auto, turned it on for this card. The table shows the runs with it off; with it on, every speed was within 1.3%. The card ran our custom undervolt with the default 195 W power cap.
Tested by our setup on 18 Nov 2026: AMD Radeon RX 5700 XT 8 GB passed through to a Debian 13 VM (6 vCPUs of an Intel Core i5-9400F), llama.cpp b12445 with Vulkan (Mesa RADV 26.1.6). We ran each model through llama-server -ngl 99 -c 8192 first, to check that all layers loaded on the GPU and to read the VRAM in use.
llama-bench -m Qwen3.5-9B-Q4_K_M.gguf -ngl 99 -p 512 -n 128 -r 5 -fa off,on -o md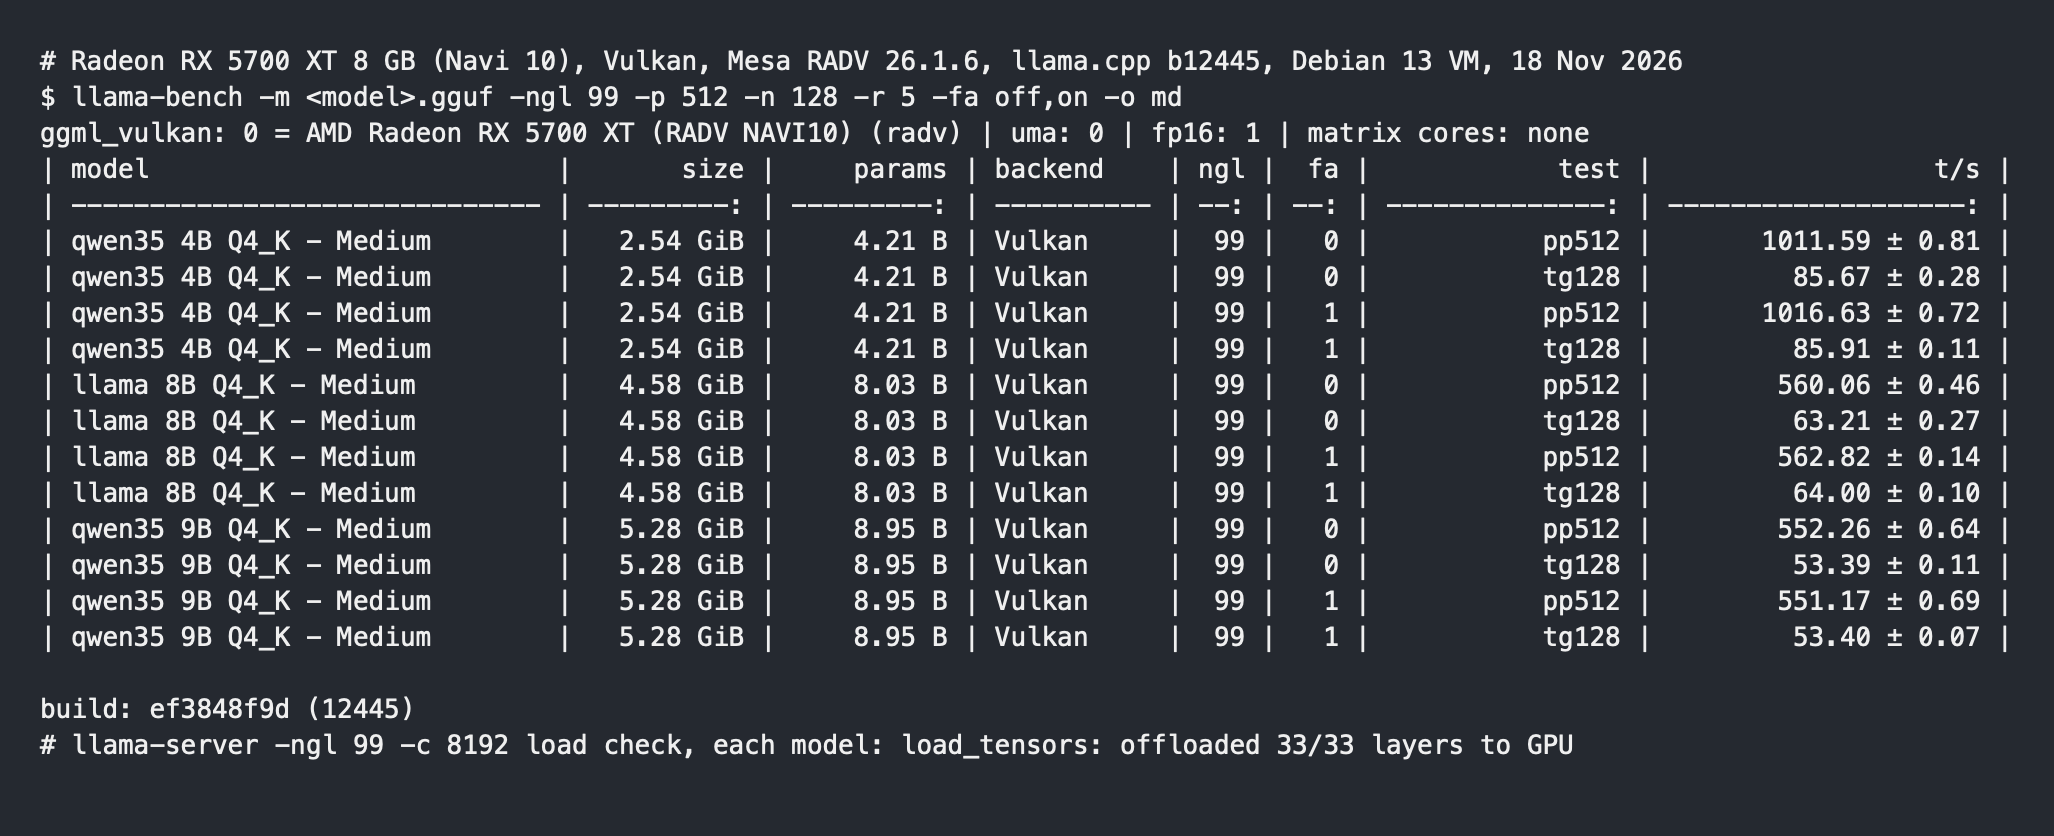
No GPU: what CPU-only speed looks like
We ran the same three models from system RAM on the same VM, with the GPU turned off. They work, slowly: 2.75 to 5.92 tokens a second, 14 to 19 times slower than the GPU at writing text. Peak memory was 1.55 to 1.76 times the file size.
| Model (4-bit) | File size | Prompt (pp512) | Generation (tg128) | Peak memory |
|---|---|---|---|---|
| Qwen3.5-4B Q4_K_M | 2.54 GiB | 59.42 t/s | 5.92 t/s | 4.03 GiB |
| Llama 3.1 8B Instruct Q4_K_M | 4.58 GiB | 32.92 t/s | 3.95 t/s | 8.04 GiB |
| Qwen3.5-9B Q4_K_M | 5.28 GiB | 32.25 t/s | 2.75 t/s | 8.19 GiB |
Each figure is the mean of 5 runs. Other VMs share the host, and they took 7% of the CPU time on average during the run, so treat these as a rough guide. At 2.75 to 3.95 tokens a second, a 200-token answer from the 8B or 9B model takes about 50 to 73 seconds.
Tested by our setup on 18 Nov 2026: the same Debian 13 VM (6 vCPUs of an Intel Core i5-9400F, 15.6 GiB RAM), llama.cpp b12445, CPU only. -dev none keeps the GPU out of the run. We read peak memory from the process’s VmHWM once a second.
llama-bench -m Qwen3.5-9B-Q4_K_M.gguf -dev none -ngl 0 -t 6 -p 512 -n 128 -r 5 -o mdApple silicon Macs can also run models on their GPU: Ollama’s macOS docs list Apple M-series chips with CPU and GPU support, and Intel Macs as CPU only. On an 8 GB M1 MacBook Air, llama.cpp ran Qwen3.5-4B on the GPU through Metal at 157.64 tokens a second for the prompt and 13.91 for generation, with 1.84 GiB peak memory. Other jobs were running on the Air at the time. We did not run larger models on it.
Tested by our setup on 18 Nov 2026: Apple M1 MacBook Air, 8 GB, macOS 27.3, Homebrew llama.cpp 1.0.0 (build 12359), llama-bench -ngl 99 -p 512 -n 128 -r 3.
Uncensored AI models for 2026: open weights to run locally
Popular self-hostable models in 2026
The table covers current open-weight models from Qwen, Llama, Gemma, Mistral and Phi, plus OpenAI’s gpt-oss. Dates are when each Hugging Face repository was created.
| Model | Parameters | On Hugging Face since | License | 4-bit file | Fits in |
|---|---|---|---|---|---|
| Qwen3.5-4B | 4.66B | 27 Feb 2026 | Apache 2.0 | 2.74 GB | 8 GB |
| Llama 3.1 8B Instruct | 8.03B | 18 Jul 2024 | Llama 3.1 Community License, gated | 4.92 GB | 8 GB |
| Qwen3.5-9B | 9.65B | 27 Feb 2026 | Apache 2.0 | 5.68 GB | 8 GB |
| Gemma 4 12B | 11.96B | 23 May 2026 | Apache 2.0 | 6.98 GB | 12 GB |
| Ministral 3 14B | 13.9B | 31 Oct 2025 | Apache 2.0 | about 8.5 GB (estimate) | 12 GB |
| Phi-4 | 14.66B | 11 Dec 2024 | MIT | about 9 GB (estimate) | 12 GB |
| gpt-oss-20b | 21B (3.6B active) | 4 Aug 2025 | Apache 2.0 | 12.11 GB | 16 GB |
| Mistral Small 3.2 24B | 24.0B | 19 Jun 2025 | Apache 2.0 | about 14.7 GB (estimate) | 24 GB |
| Qwen3.8-27B | 27.78B | 5 Aug 2026 | Apache 2.0 | 16.56 GB | 24 GB |
| Gemma 4 31B | 31.3B | 11 Mar 2026 | Apache 2.0 | 17.65 GB | 24 GB |
| Llama 3.3 70B Instruct | 70.55B | 26 Nov 2024 | Llama 3.3 Community License, gated | 42.52 GB | 2 × 24 GB or 48 GB |
The 4-bit files are Q4_K_M, except gpt-oss-20b (MXFP4, the format it ships in), Qwen3.8-27B (Unsloth’s UD-Q4_K_M) and Gemma 4 (Google’s own QAT Q4_0 files). The three estimates are parameter count × 4.89 bits per weight, the Q4_K_M rate in llama.cpp’s table. We have not checked those files.
What changed by family since March 2025:
- Qwen (Alibaba): Qwen2 (June 2024) had already given way to Qwen2.5 (September 2024) by March 2025. Qwen3 followed in April 2025, Qwen3.5 in February 2026 and Qwen3.8-27B in August 2026. Qwen’s largest new releases, Qwen3.8-Flash-Next (180B, August 2026) and Qwen3.8-2.4T, use custom licenses and are far beyond home hardware.
- Gemma (Google): Gemma 4 arrived in March 2026 and now comes in E2B, E4B, 12B (added in May), 26B A4B and 31B sizes. 26B A4B is a mixture-of-experts model. Gemma 4 is Apache 2.0, while Gemma 3 used Google’s own Gemma terms.
- Phi (Microsoft): Phi-3 was replaced by Phi-4 (14.7B, December 2024) and Phi-4-mini (3.8B, February 2025), both MIT. The newest Phi release on the Hub is Phi-4-reasoning-vision-15B (January 2026).
- Mistral: Ministral 3 (3B, 8B and 14B) and Mistral Small 3.2 24B are Apache 2.0. Mistral Small 4 (119B) and Mistral Large 4 (1T total, custom license) are server-class.
- Llama (Meta): Meta’s newest LLM on Hugging Face is still Llama 4 from April 2025. Llama 4 Scout has 109B parameters with 17B active, more than one consumer GPU holds, so Llama 3.1 8B and Llama 3.3 70B stay in the table. Llama models are open-weight under Meta’s community licenses, not open source in the usual sense. Companies with more than 700 million monthly active users must ask Meta for a license, and you need to accept the terms on Hugging Face before you can download them.
- gpt-oss (OpenAI): gpt-oss-20b and gpt-oss-120b arrived in August 2025 under Apache 2.0.
Software infrastructure
Inference frameworks
These are the tools that load a model and answer requests. Versions are the latest releases on 18 Nov 2026.
- llama.cpp (GitHub): C/C++ inference for CPUs and GPUs, MIT license, v1.0.0 from 13 Nov 2026. It includes
llama-server, which answers chat requests over HTTP. The project moved fromggerganovto theggml-orgaccount; the old links redirect. - Ollama (Website): a command-line runner and local API with a library of ready-made models. MIT license, v0.40.16 from 9 Nov 2026. It is a native app and service, and Docker is one of several install options.
ollama.ainow redirects toollama.com. - Open WebUI (GitHub): a browser chat interface with user accounts that connects to Ollama. v0.13.4 from 17 Nov 2026, under the Open WebUI License (BSD-3 style with extra conditions).
- vLLM (GitHub): a high-throughput serving engine with PagedAttention, built for GPU servers. Apache 2.0, v0.34.0 from 16 Nov 2026. We did not test it.
- textgen (GitHub): formerly text-generation-webui, now described as an “open-source desktop app for local LLMs”, with portable builds. AGPL-3.0, v4.9 from 20 May 2026.
- LocalAI (GitHub): a self-hosted API in the OpenAI, Anthropic and ElevenLabs formats. MIT license, v4.12.1 from 23 Oct 2026. Its README says no GPU is required.
Deployment options
- Direct installation: install the tool on Linux, Windows or macOS.
- Docker containers: simpler upgrades and clean removal. Docker publishes container ports on all host addresses by default, so write
127.0.0.1:in front of every port you publish. - Kubernetes: for multi-machine or enterprise deployments. Not covered here.
- A home server: an always-on machine on your network that every device in the house can use.
Build a home server: a beginner’s guide
Step-by-step setup guide
Pick one of the three routes below. The commands are for Debian or Ubuntu unless noted. Whichever you choose, keep the server on 127.0.0.1 until you have put a login in front of it. Before you start, make sure the machine has enough cooling and power for long runs.
Option 1: Ollama and Open WebUI with Docker
This gives you a model server and a ChatGPT-style web page, both reachable only from the machine itself. If you run CasaOS, see our walkthrough for Ollama and Open WebUI on CasaOS. Save this as compose.yml:
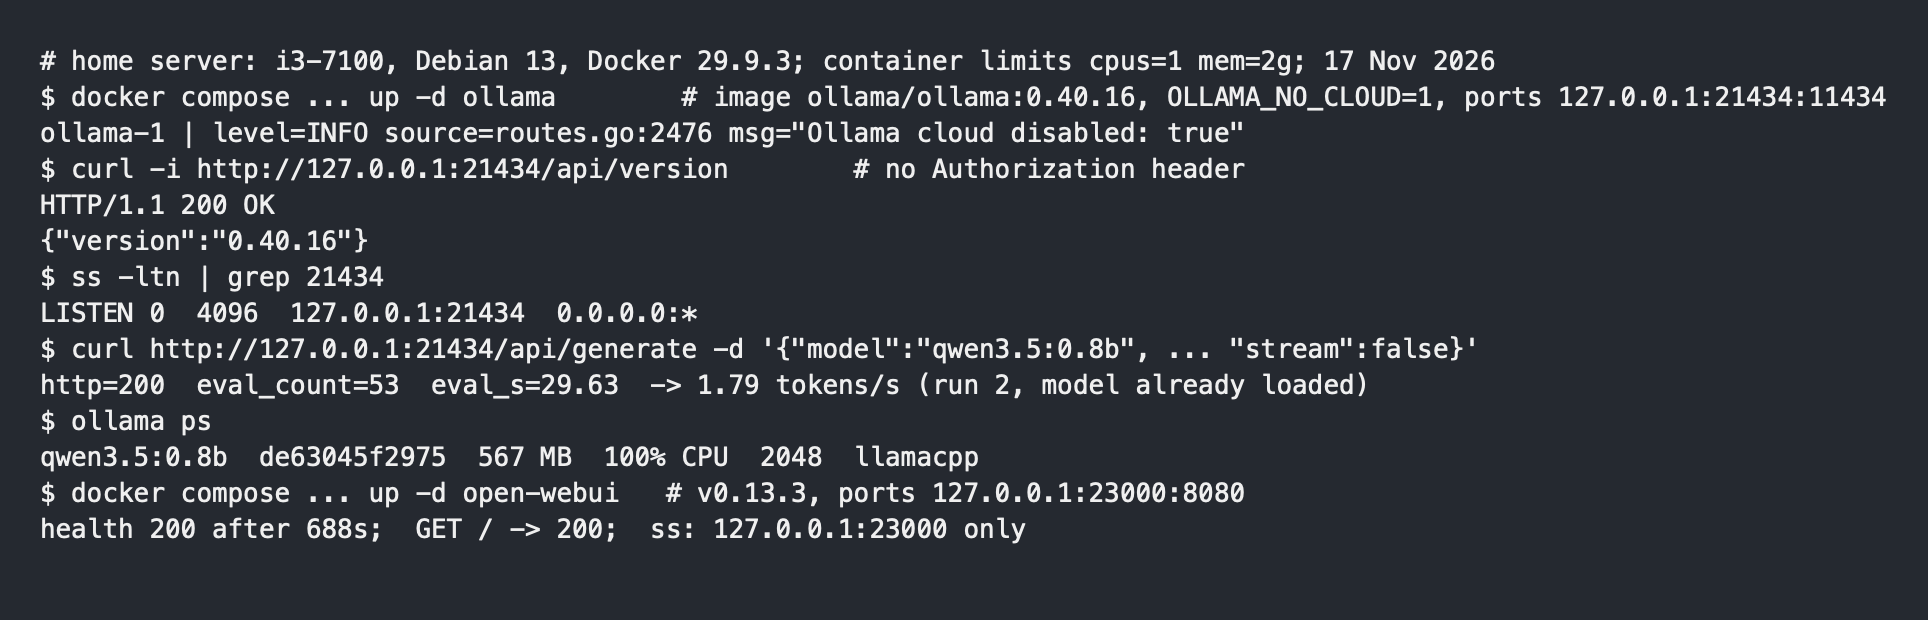
Tested by our setup on 17 Nov 2026: our home server (Intel Core i3-7100, Debian 13, Docker 29.9.3). Our run also capped each container at 1 CPU and 2 GB, which this copy leaves out. Host ports 21434 and 23000 are the ones we used; any free port works, as long as it keeps the 127.0.0.1: prefix.
services:
  ollama:
    image: ollama/ollama:0.40.16
    environment:
      OLLAMA_NO_CLOUD: "1"
    ports:
      - "127.0.0.1:21434:11434"
    volumes:
      - ollama:/root/.ollama
  open-webui:
    image: ghcr.io/open-webui/open-webui:v0.13.3
    environment:
      OLLAMA_BASE_URL: http://ollama:11434
    ports:
      - "127.0.0.1:23000:8080"
volumes:
  ollama:
OLLAMA_NO_CLOUD=1 turns off Ollama’s cloud models; the log then shows Ollama cloud disabled: true. The file pins Open WebUI v0.13.3, the version we ran in Docker; v0.13.4 came out on 17 Nov 2026. This file keeps no Open WebUI data between rebuilds. To keep accounts and chats, add a volume for /app/backend/data, as Open WebUI’s README does. Its README command publishes port 3000 on all interfaces, so add 127.0.0.1: there too.
Start both, pull a model and send a test request:
Tested by our setup on 17 Nov 2026: our home server (Intel Core i3-7100, Debian 13, Docker 29.9.3). We started the two services one at a time. The request needed no login: Ollama’s API has none.
docker compose up -d
docker compose exec ollama ollama pull qwen3.5:0.8b
curl http://127.0.0.1:21434/api/generate -d '{"model":"qwen3.5:0.8b","prompt":"In two sentences, explain what a GGUF file is.","stream":false,"think":false,"options":{"temperature":0,"seed":42,"num_predict":128,"num_ctx":2048}}'
We used the tiny qwen3.5:0.8b (a 1.3 GB download) only to check the setup. On one CPU core it wrote 1.79 tokens a second, and its answer about GGUF was wrong. For real use, pick a model that fits your memory, such as qwen3.5:9b (6.6 to 7.6 GB on Ollama’s tags page). On our 8 GB RX 5700 XT it loaded 100% on the GPU at Ollama’s default 4,096-token context. Open WebUI answers at http://127.0.0.1:23000. Its first start took about 11 minutes on our server, mostly to download an embedding model from huggingface.co. We did not create an account or chat through it there. In a later run on the GPU machine, with Open WebUI in single-user mode, a chat request through its API got an answer from Ollama.
Without Docker, Ollama’s Linux install is one line:
From the official docs: Ollama on Linux, checked 17 Nov 2026. Not run by us.
curl -fsSL https://ollama.com/install.sh | shOn the GPU machine we unpacked Ollama 0.40.16 from its official Linux tarball into a folder and started it from there. It found the RX 5700 XT through Vulkan with no setup, and qwen3.5:4b and qwen3.5:9b each loaded 100% on the GPU.
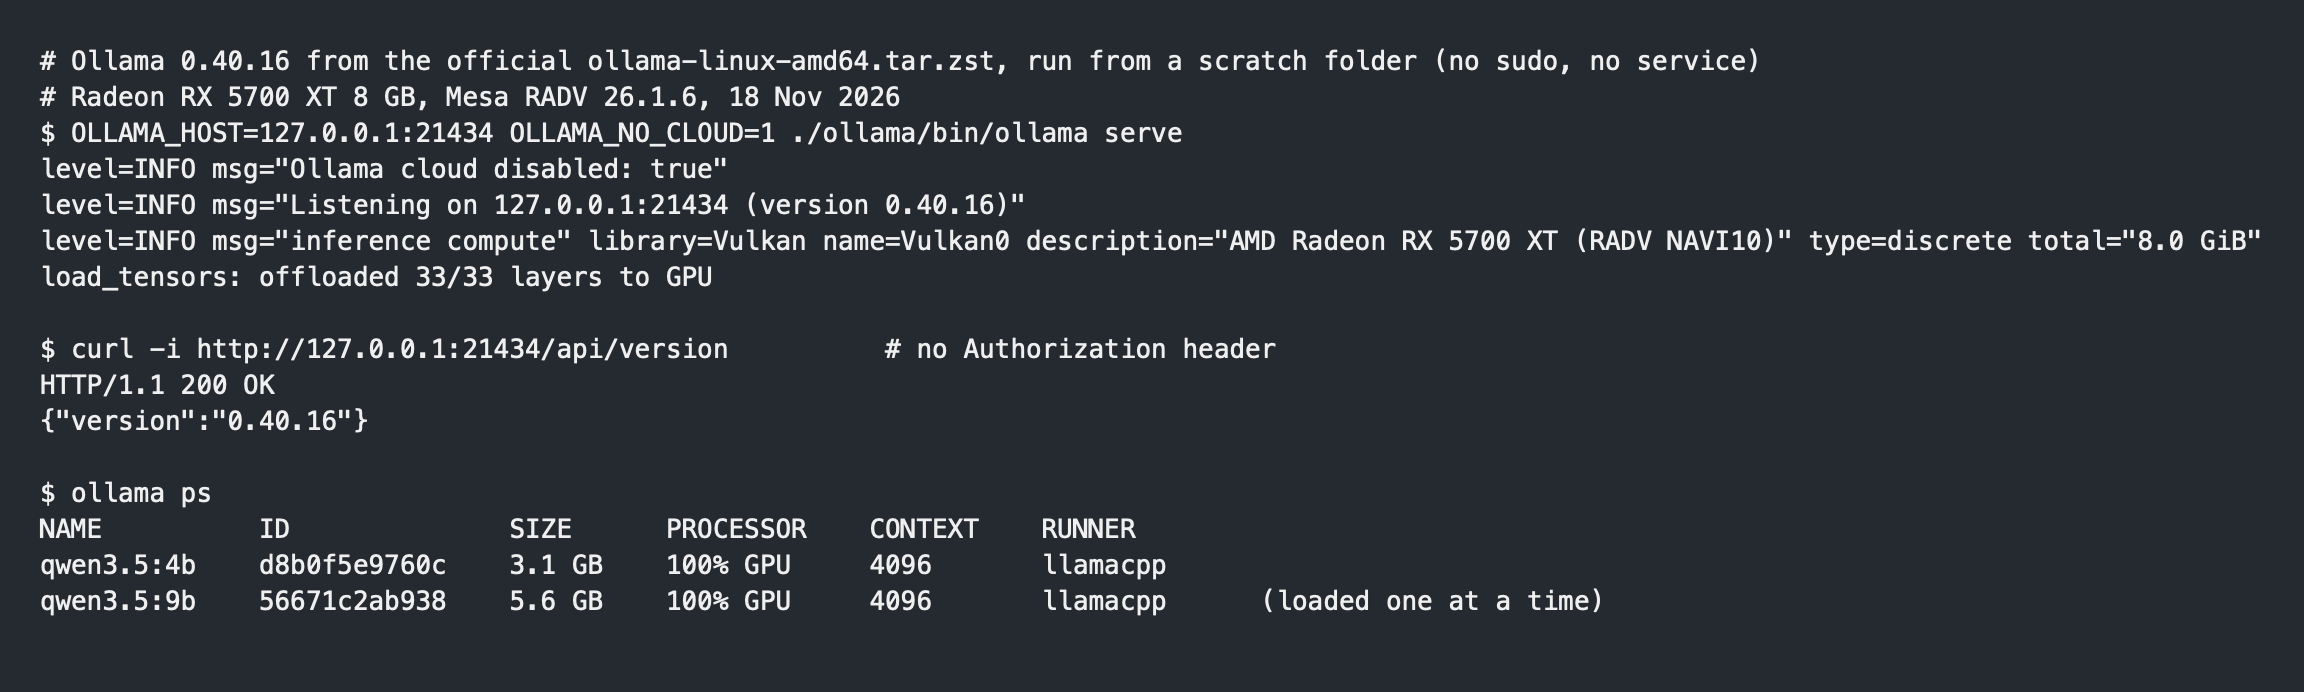
A native install binds to 127.0.0.1 port 11434 by default. To turn off cloud models there, set "disable_ollama_cloud": true in ~/.ollama/server.json or set OLLAMA_NO_CLOUD=1, as Ollama’s FAQ describes.
Option 2: llama.cpp’s built-in server
llama.cpp runs a GGUF file directly, with no model library in between. Download a file from Hugging Face:
Tested by our setup on 18 Nov 2026: Debian 13 VM with an AMD Radeon RX 5700 XT 8 GB. Our script added retry flags and checked the file’s SHA-256 against the hash Hugging Face lists for it.
curl -L -o Qwen3.5-9B-Q4_K_M.gguf https://huggingface.co/unsloth/Qwen3.5-9B-GGUF/resolve/main/Qwen3.5-9B-Q4_K_M.ggufThen start the server with an 8K context and check that it answers:
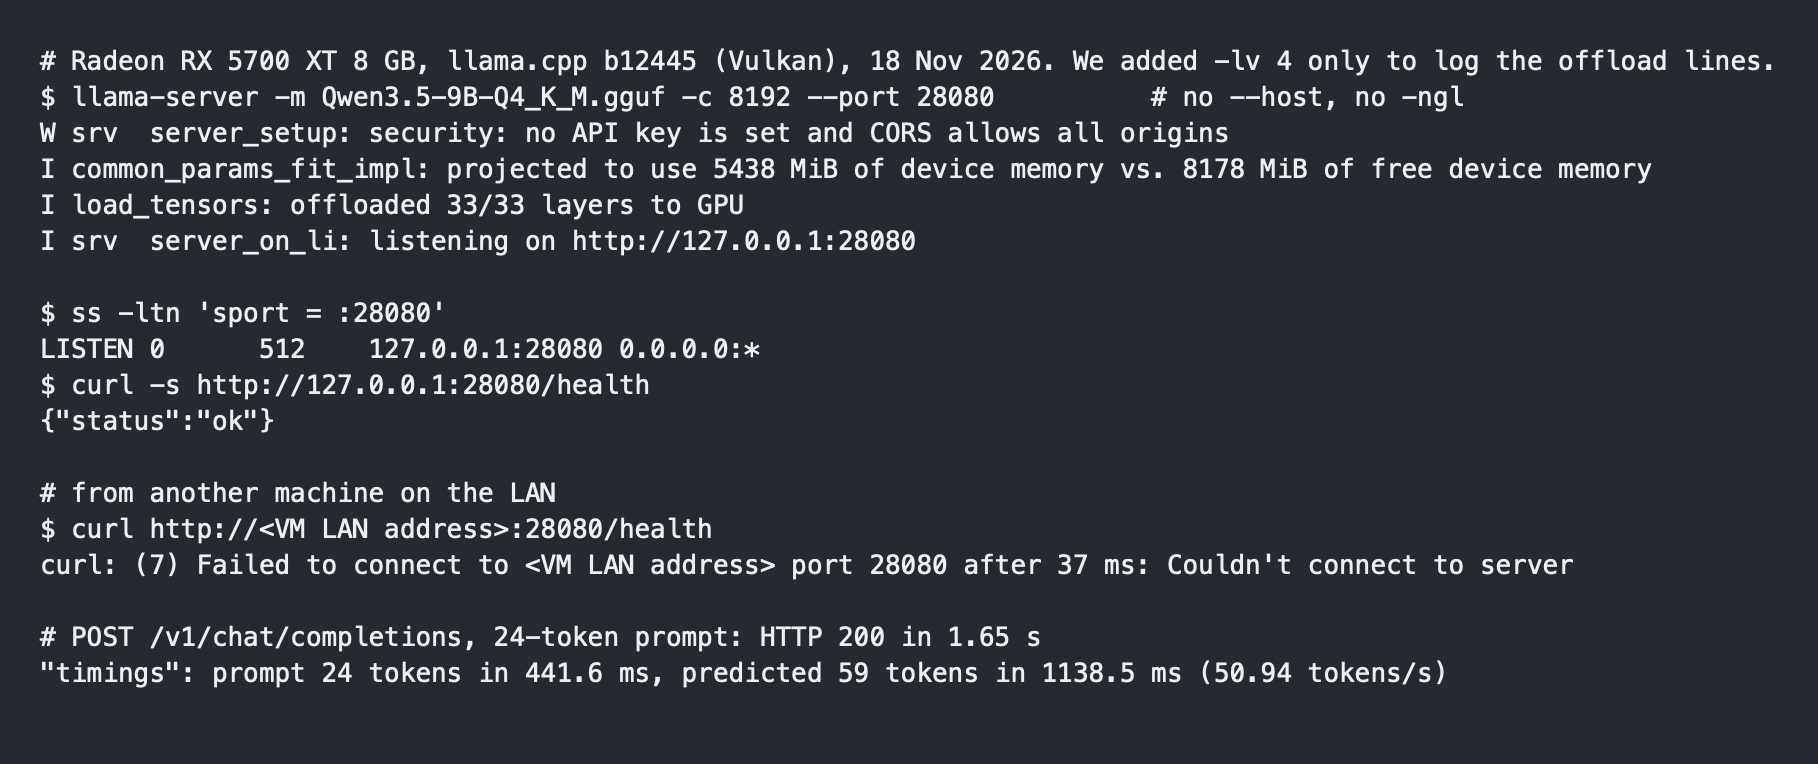
Tested by our setup on 18 Nov 2026: AMD Radeon RX 5700 XT 8 GB in a Debian 13 VM, llama.cpp b12445 with Vulkan. We added -lv 4, which only adds the model loading lines to the log.
llama-server -m Qwen3.5-9B-Q4_K_M.gguf -c 8192 --port 28080
curl -s http://127.0.0.1:28080/health
With no --host option, it listened on 127.0.0.1 only, and a request from another machine on the LAN was refused. It also warned at startup that no API key is set and that CORS allows all origins. -ngl sets how many layers go to VRAM, and its default is auto: with no -ngl option, llama-server put all 33 layers on our 8 GB GPU. One chat request with a 59-token answer took 1.65 seconds. We did not test a model too big for the card, where only some layers fit.
Option 3: textgen (formerly text-generation-webui)
textgen gives you a web UI plus an OpenAI-compatible API. First install the build tools:
Tested by our setup on 17 Nov 2026: Debian 13 and Ubuntu 24.04 containers on our home server (Intel Core i3-7100, Docker 29.9.3). We ran it as root with apt-get, so without sudo.
sudo apt update
sudo apt install python3-pip python3-venv git cmake build-essential
textgen’s portable route only needs git and python3-venv. cmake and build-essential are for building llama.cpp from source. Then clone it, make a virtual environment and start it:
Tested by our setup on 17 and 18 Nov 2026. On 17 Nov we ran these steps in Debian 13 and Ubuntu 24.04 containers on our home server (Intel Core i3-7100, Docker 29.9.3), at commit c93f887, cloned from the old text-generation-webui URL. The UI answered on port 7860 and the API on 127.0.0.1:5000. We did not load a model. On 18 Nov we ran the git clone and cd lines below with the new URL, adding --depth 1 to the clone: it is the same repository at the same commit.
git clone https://github.com/oobabooga/textgen
cd textgen
python3 -m venv venv
source venv/bin/activate
pip install -r requirements/portable/requirements_cpu_only.txt --upgrade
python server.py --portable --api
The 2025 version ran pip install -r requirements.txt. That file was removed on 22 Apr 2025, and the command now fails with “No such file or directory”. The line above installs the CPU-only packages. For a GPU, pick the matching file in requirements/portable/ (the README’s default is requirements/portable/requirements.txt). The project is now called textgen, and the old text-generation-webui URL redirects to it. Open http://127.0.0.1:7860 and fetch a model from Hugging Face with the included download-model.py script.
Configure and secure it
- Context length: longer context uses more memory. Set it with
-cin llama.cpp ornum_ctxin Ollama. - Quantization: start with a 4-bit file (Q4_K_M) and go up only if you have memory to spare.
- GPU layers and batch size: let
-ngl autodecide first, then lower the layers or the batch size if you run out of memory. - Access: keep services on 127.0.0.1. For other devices, use a VPN rather than opening a port. For more than one user, put a login in front: Open WebUI’s accounts, or a reverse proxy with authentication. Ollama’s local API has no authentication of its own.
Optimizing performance
Quantization techniques
Quantization stores the weights in fewer bits, so the model needs less memory, at some cost in quality.
- GGUF (spec): the file format llama.cpp, Ollama and textgen load. It replaced the older GGML files.
- Q4_K_M: a good balance of size and quality, at about 4.89 bits per weight. Llama 3.1 8B is 4.58 GiB at Q4_K_M, 7.95 GiB at Q8_0 and 14.96 GiB at full 16-bit, according to llama.cpp’s quantization README.
- MXFP4: the 4-bit format gpt-oss ships in.
- AWQ and GPTQ: GPU formats used with servers such as vLLM. AutoAWQ is deprecated and its work moved into vLLM’s llm-compressor. AutoGPTQ is unmaintained, and its maintainers point to GPTQModel. The AWQ method won the MLSys 2024 best paper award.
Memory optimization
- Context length (
-c): longer context needs more memory. Set it to what you need, not the model’s maximum. - GPU offload (
-ngl): llama.cpp’s help calls it the “max. number of layers to store in VRAM”. Layers that do not fit stay in system RAM. The model still runs, but slower with every layer left in RAM. - Flash attention (
-fa): a faster attention method that uses less memory (paper). llama.cpp sets it toautoby default, so it turns on where your hardware supports it.
On our 8 GB card, both defaults worked as described: every layer of the 4B to 9B models went to VRAM, and flash attention turned on. We did not test a model that only partly fits in VRAM.
Privacy considerations
llama.cpp’s server was local-only by default in our test, and Ollama’s docs say the same of a native install. Docker publishes ports on every interface unless you add 127.0.0.1:. These steps close the gaps we found:
- Local models only: Ollama offers cloud models and web search alongside local ones. Turn them off with
OLLAMA_NO_CLOUD=1or"disable_ollama_cloud": true. LM Studio’s docs say “Nothing you enter into LM Studio when chatting with LLMs leaves your device”. - Bind to localhost: keep every published port on
127.0.0.1:, as in the compose file above. Open WebUI started with its README’suvxcommand listens on0.0.0.0port 8080 by default, so add--host 127.0.0.1. Check withss -ltnon Linux: the address should read127.0.0.1, not0.0.0.0. - Put a login in front: Ollama’s API answered our requests with no authentication, as its docs say. llama-server warns at startup that no API key is set. Open WebUI refused API calls without a token (HTTP 401).
- Expect outbound downloads: even a local stack reaches out on first start. Open WebUI downloaded an embedding model from huggingface.co before it would answer. For an air-gapped machine, download everything first.
- Model provenance: download from the publisher’s own account or a known converter, and check the file’s SHA-256 against the hash on Hugging Face.
- Data handling and updates: set retention and deletion rules for chat logs, and keep the inference software up to date for security fixes.
Cost analysis: self-hosting vs API services
Self-hosting has a fixed cost and APIs charge per token. Which is cheaper depends on how much you use and which API model you compare against. Work it out with three formulas:
- API cost per month = (input tokens ÷ 1M × input price) + (output tokens ÷ 1M × output price)
- Self-hosting cost per month = hardware ÷ months you will keep it + electricity (watts × hours ÷ 1,000 × your tariff per kWh) + upkeep
- Months to recover the hardware = hardware ÷ (API cost per month - self-hosting running cost per month)
If the API costs less per month than your power and upkeep, the hardware never pays for itself on cost alone.
Example scenario: medium-sized business (100,000 queries a month)
This is the 2025 version’s scenario with its maths fixed. Assume 100,000 queries a month at 2,000 tokens each, split 1,500 input and 500 output. That is 150M input and 50M output tokens a month.
Self-hosting, with the 2025 version’s figures. We did not measure these, so treat them as assumptions:
- Hardware: $3,000, spread over 3 years ($83 a month)
- Electricity: $40 a month. For scale, our RX 5700 XT’s own power reading went up to 199 W in the benchmarks. That reading covers the card alone; we had no meter at the wall
- Upkeep: $60 a month
- Total: about $183 a month, or $100 a month once the hardware is paid for
API, at OpenAI’s standard list prices on 17 Nov 2026:
| API model | Input / output per 1M tokens | Cost per month | Months to recover a $3,000 build |
|---|---|---|---|
| gpt-4o (deprecated, shuts down 14 Jan 2027) | $2.50 / $10.00 | $875 | 3.9 |
| gpt-5.4-mini | $0.75 / $4.50 | $337.50 | 12.6 |
| gpt-6-luna (OpenAI’s named replacement for gpt-4o) | $0.10 / $0.50 | $40 | Never |
The 2025 version priced GPT-4o at “$0.04 per 1K tokens” and came to $800 a month, with a 4 to 5 month break-even. The price was wrong: OpenAI lists GPT-4o at $2.50 per 1M input and $10.00 per 1M output tokens. So was the sum: $0.04 × 2 × 100,000 is $8,000, not $800. At the real price, the break-even against GPT-4o is 3.9 months, but GPT-4o shuts down in January 2027. Against gpt-6-luna, the scenario never breaks even, because $40 a month is less than the $100 of power and upkeep.
Speed is the other question. 200M tokens a month is about 77 tokens a second around the clock: 57.87 input and 19.29 output. At our measured speeds, one 8 GB RX 5700 XT would be busy about 47% of the time with Qwen3.5-9B, 41% with Llama 3.1 8B and 28% with Qwen3.5-4B. We worked this out from the benchmark numbers and did not run the workload. The sum assumes an even load, one request at a time, and the same prompt speed at 1,500 tokens as at the 512 we measured. On a CPU alone, the same models would fall far short. A small local model also won’t match an API model on quality, so compare the answers as well as the prices.
Self-hosting wins when your data must not leave your network, when you already own suitable hardware, or when you run steady heavy work that would otherwise go to a mid-priced API model. An API wins for light or bursty use, and whenever the cheapest API models are good enough for the job.
Advanced use cases
- Model fine-tuning: adapt a model to your domain. LoRA trains small adapter weights instead of the whole model. Check the base model’s license first.
- Multi-model orchestration: run different models for different tasks, such as a small fast model for autocomplete and a larger one for chat.
- Retrieval-augmented generation (RAG): combine a local model with a vector database so it can answer from your own documents. See our guide to automating RAG pipelines with Bash.
- Hybrid deployments: keep private work on the local model and send the rest to an API.
Troubleshooting common issues
- Out of memory errors: use a smaller quantization, reduce the context (
-c), put fewer layers on the GPU (-ngl) or lower the batch size. - Slow inference: check that the layers are actually on the GPU (llama.cpp’s log says how many, for example
offloaded 33/33 layers to GPU), check for thermal throttling, and shorten prompts. On our test VM, the GPU wrote text 14 to 19 times faster than 6 CPU cores. - Model hallucinations: try a newer or larger model, or use RAG. Small models get facts wrong confidently.
- GPU not used: update the drivers. CUDA is NVIDIA only. For AMD, Ollama has a
:rocmDocker image that needs/dev/kfdand/dev/dri. Ollama also bundles Vulkan support: on our RX 5700 XT, which is not on Ollama’s ROCm list, it used Vulkan with no setup. - Reachable from the network by accident: run
ss -ltnand look for0.0.0.0or[::]next to your port.
Useful resources
- r/LocalLLaMA (Subreddit): a community forum for running models locally.
- Hugging Face (Website): model downloads, model cards and licenses.
- Ollama library (Website): ready-made model tags with their download sizes.
- LM Studio (Website): a desktop app for running models locally. Its docs say it can run fully offline once you have the model files. Not tested by us.
- Jan (Website): an open-source ChatGPT alternative for the desktop, Apache 2.0, v0.8.8 from 28 Oct 2026. Not tested by us.
- GPT4All (Website): a desktop app for local models. It has had no release since v3.10.0 on 25 Feb 2025.
Future-proofing your setup
- Buy for memory: VRAM decides which models you can run.
- Containerized deployment: makes it easy to switch models and update the software.
- Benchmark regularly: re-run
llama-benchafter updates, and compare answers with current API models. - Follow the open-weight releases: every family in the models table has released newer models since March 2025.
Conclusion
Ollama, llama.cpp and textgen each install with a few commands, and current open-weight models from 4B to 31B fit consumer hardware at 4-bit. Privacy is the best reason to self-host, as long as you keep the ports local and the cloud features off.
Saving money is a weaker reason. In our example, the cheapest API model we priced costs less per month than the power and upkeep of a home box. If cost is why you want to self-host, do the sums before you buy hardware.
Changes
- 18 Nov 2026: replaced Llama 3, Phi-3, Qwen2 and the unnamed Mistral and Gemma picks with current models and their licenses, and sized the hardware tiers by memory with a VRAM table. Dropped the unsourced CPU core counts and build prices.
- 18 Nov 2026: fixed the text-generation-webui install, whose
requirements.txtno longer exists, and added Ollama with Open WebUI and llama.cpp’s server, each bound to 127.0.0.1. - 18 Nov 2026: corrected the cost example (wrong GPT-4o price and a tenfold multiplication error), compared against current OpenAI models and replaced the single break-even figure with a formula.
- 18 Nov 2026: added our own test results (speed and memory on an 8 GB AMD Radeon RX 5700 XT, on the same machine CPU-only and on an M1 MacBook Air, plus the install steps in containers) and a “Tested by our setup” box. Switched the textgen clone URL to
github.com/oobabooga/textgenafter testing it.
Frequently asked questions
Is self-hosting LLMs difficult for non-technical users?
Less than it used to be. LM Studio and Jan are desktop apps that download and run models on your own computer, and Ollama installs on Linux with one command. The harder parts are choosing a model that fits your memory and keeping the server off your network until it has a login. We have not tested LM Studio or Jan for this guide.
Can self-hosted LLMs match the quality of cloud API services?
Not across the board, and we have not benchmarked quality for this guide. The dense models that fit one consumer GPU at 4-bit top out at about 27B to 31B parameters. The largest open-weight models are far bigger: Mistral Large 4 has 1T parameters in total. Small models also get facts wrong: in our test, a 0.8B model gave a confident but wrong answer to "what is a GGUF file?". Try a model on your own prompts before you buy hardware for it.
How often do I need to upgrade my hardware?
There is no fixed cycle. Memory decides it: when the models you want no longer fit your VRAM, you can use a smaller quantization, keep some layers in system RAM (slower), or upgrade. An 8 GB card already covers the 4B to 9B models: on ours, all three we tried ran with every layer on the GPU. Mixture-of-experts models stretch a card further. gpt-oss-20b has 21B parameters but only 3.6B active per token, and its model card says it runs within 16 GB of memory.
Are there legal concerns with self-hosting open-source models?
Check the license on each model card. Most current open-weight models are permissive: Qwen3.5, Qwen3.8-27B, Gemma 4, gpt-oss, Ministral 3 and Mistral Small 3.2 use Apache 2.0, and Phi-4 uses MIT. Llama is the main exception: Meta's community licenses require companies with more than 700 million monthly active users to ask Meta for a license, and the downloads are gated. Some large releases, such as Mistral Large 4 and Qwen3.8-Flash-Next, use custom licenses.
Can I use self-hosted LLMs for sensitive data in regulated industries?
Self-hosting gives you control over where data goes, which can make compliance easier, but it does not make you compliant by itself. Use local models only, turn off cloud features (for Ollama, OLLAMA_NO_CLOUD=1), bind every service to 127.0.0.1 or put a login in front of it, and set retention rules for logs and chat history. Check your obligations with a lawyer.
Comments
No comments yet.
Report